oaklight/llm-rosetta-gateway
Universal LLM API gateway — convert between OpenAI, Anthropic, Google GenAI formats on the fly.
10K+
oaklight/llm-rosetta-gateway repository overview
LLM-Rosetta
English | 中文
Any supported LLM API format in, any supported format out — with your model
sources under your control. LLM-Rosetta translates between the wire formats of
OpenAI, Anthropic, Google and other providers through a central Intermediate
Representation (IR). Use it as a Python library, or run the self-hosted gateway
as a backend for Claude Code, Codex CLI, Aider and OpenAI-compatible clients.
The gateway keeps your upstream configuration, credentials and routes in your
deployment; LLM-Rosetta itself does not add a hosted aggregator to the path. On
Python 3.11+ it needs no third-party runtime dependency; 3.10 adds only
typing_extensions, a backport of the standard library's typing module.
Why
Supporting N formats pairwise takes O(N²) adapters — every format pair needs its own conversion code. With an IR in the middle, each format needs one bidirectional converter to and from the IR, and any-to-any conversion follows:
Provider A ──→ IR ──→ Provider B
Provider C ──→ IR ──→ Provider D
Requests, responses, streamed chunks and tool calls all travel the same path. Adding a new wire format requires one converter; adding a new provider on an existing format requires one shim — not one adapter per existing provider.
Why Not Just Use a Provider That Speaks Several Formats?
If one client and one provider natively share a dialect, you do not need a translator. LLM-Rosetta covers the cases that pairing leaves open.
- Compatibility layers are partial. A vendor's
responsesormessagesendpoint implements the fields that vendor chose. Other fields —store, thinking signatures, cache controls — may be rejected, carried differently, or dropped. The shims record what each upstream accepts, then adapt the request or report the loss. - Conversations move between providers. Switching provider mid-session means converting the transcript you already have: tool calls, reasoning blocks, images and cache markers. Opaque artifacts such as signatures and provider-minted IDs cannot be made valid for another vendor; they are preserved, stripped or replaced, and the loss is reported.
- Some pairings have no native path. Codex CLI speaks Responses; a provider that does not implement that dialect cannot serve it. Claude Code speaks Messages; providers that added a compatibility endpoint cover the common case, but field coverage still varies.
If one stable client-provider pairing already works, do not add a translator. Use LLM-Rosetta when clients or providers need to be independently replaceable — and expect some conversions to be lossy.
Why Not LiteLLM or OpenRouter?
They solve adjacent problems but center on different concerns.
OpenRouter is primarily a hosted service. In its standard setup, OpenRouter manages provider access and routing, and your traffic passes through its service; it also offers bring-your-own-key options. That is its strength: you reach models without signing up with each vendor. LLM-Rosetta assumes the opposite — you own every upstream credential and run the gateway yourself.
LiteLLM is self-hostable and offers broad provider coverage. It also provides team keys, budgets and spend tracking. Its core interface is primarily OpenAI-shaped; other formats are mapped onto that centre. LLM-Rosetta's IR belongs to no vendor: every supported format can sit on either side, so the client's dialect and the model source stay independent, and your application can keep its payload in IR. Losses the converter detects are reported as warnings instead of being dropped silently.
Coverage on both sides changes quickly; check their current docs.
- Choose OpenRouter if you do not want to hold provider accounts at all.
- Choose LiteLLM if you need broad provider coverage or team-level cost controls.
- Choose LLM-Rosetta if you own your model sources and need to serve clients in different formats from them, with conversion loss you can inspect.
Three Levels and a Toolbox
| Toolbox | Raw converter | Pipeline | Gateway | |
|---|---|---|---|---|
| Use case | Convert one IR value or tool | Translate one leg inside your own loop | Source → IR → target in one call | HTTP proxy for any client |
| Entry point | tool_ops, transforms, capabilities | ChatCompletionsConverter() | convert() / ConversionPipeline | llm-rosetta-gateway |
| Provider call | You | You | You | The gateway |
| Routing, keys, admin | — | — | — | Built in |
All three levels share the same IR and converters, and the toolbox operates on
that same IR. Start at the level you need and move up without rewriting the
translation. tool_ops converts one tool definition, choice, call or result
between a provider dialect and IR; transforms and capabilities apply one
field or capability pass without building a converter.
Python 3.11+ needs no third-party runtime dependency; 3.10 adds only
typing_extensions, a backport of the standard library's typing module. That is unusual for
a multi-provider gateway, and it means the same pipeline moves between
applications and deployments without a dependency graph to resolve; only the
Python version has to match.
Raw Converter
from llm_rosetta import ChatCompletionsConverter, MessagesConverter

openai_request = {
    "model": "gpt-4o",
    "messages": [{"role": "user", "content": "Hello!"}],
}

# OpenAI Chat Completions → IR → Anthropic Messages
ir = ChatCompletionsConverter().request_from_provider(openai_request)
anthropic_request, warnings = MessagesConverter().request_to_provider(ir)
Call the provider with your own client, then convert the response into the IR:
ir_response = MessagesConverter().response_from_provider(response)
Streaming conversion is stateful; the converter keeps a StreamContext across
chunks. See Streaming.
Pipeline
convert() resolves the shims for the source and target and runs the full
source → IR → target path in one call. ConversionPipeline exposes the same
path through convert_request() and convert_response() when you need to keep
the pipeline object, pass a shim, or read pipeline.warnings.
from llm_rosetta import convert, detect_provider

detect_provider(openai_request)                          # 'chat_completions'
anthropic_request = convert(openai_request, target_provider="messages")
The pipeline resolves both shims, so a target shim's defaults can make its body
differ from the raw converter's — Anthropic's default cache_control breakpoint
is one example. The IR and converters are shared; the shim layer is the
difference.
Because the IR is a typed, provider-neutral payload, you can keep conversation
history, routing state or evaluation data in IR and render it to a provider's
dialect only at the call boundary. Switching providers changes the renderer, not
your application's data model. The core has no third-party dependency on
Python 3.11+ (3.10 adds typing_extensions), and because the payload stays in
IR, supporting another API format does not add a dependency or a format-specific
branch to your application.
Gateway
pip install llm-rosetta-gateway
llm-rosetta-gateway init     # writes a template config
llm-rosetta-gateway          # serves http://localhost:8765
List your upstreams under providers, and map each model name clients send to a
provider under models. The gateway routes by model name and converts between
the source and upstream formats:
{
  "providers": {
    "my-openai":    { "type": "chat_completions", "api_key": "${OPENAI_API_KEY}",    "base_url": "https://api.openai.com/v1" },
    "my-anthropic": { "type": "messages",         "api_key": "${ANTHROPIC_API_KEY}", "base_url": "https://api.anthropic.com" }
  },
  "models": {
    "gpt-4o": "my-openai",
    "claude-sonnet-4-5": "my-anthropic"
  },
  "server": {
    "host": "127.0.0.1",
    "port": 8765,
    // Local demo only. For a shared deployment, bind 0.0.0.0 behind your
    // own network controls, create a gateway key in /admin, and send it
    // in the format's native auth header.
    "open_on_no_keys": true
  }
}
Send an OpenAI-format request to an Anthropic model — the gateway translates both directions, including streaming:
curl http://localhost:8765/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model": "claude-sonnet-4-5", "messages": [{"role": "user", "content": "Hello!"}]}'
With a gateway key configured, a shared deployment accepts the key in the
format's native header — Authorization: Bearer <key> for OpenAI-style routes,
x-api-key: <key> for Messages, x-goog-api-key: <key> (or ?key=<key>) for
Google — and also accepts a plain Authorization: Bearer on any route, the form
most CLI clients send. The reverse does not hold: an OpenAI-style route rejects
x-api-key.
The built-in console at http://localhost:8765/admin/ manages providers,
models, API keys and observability data:
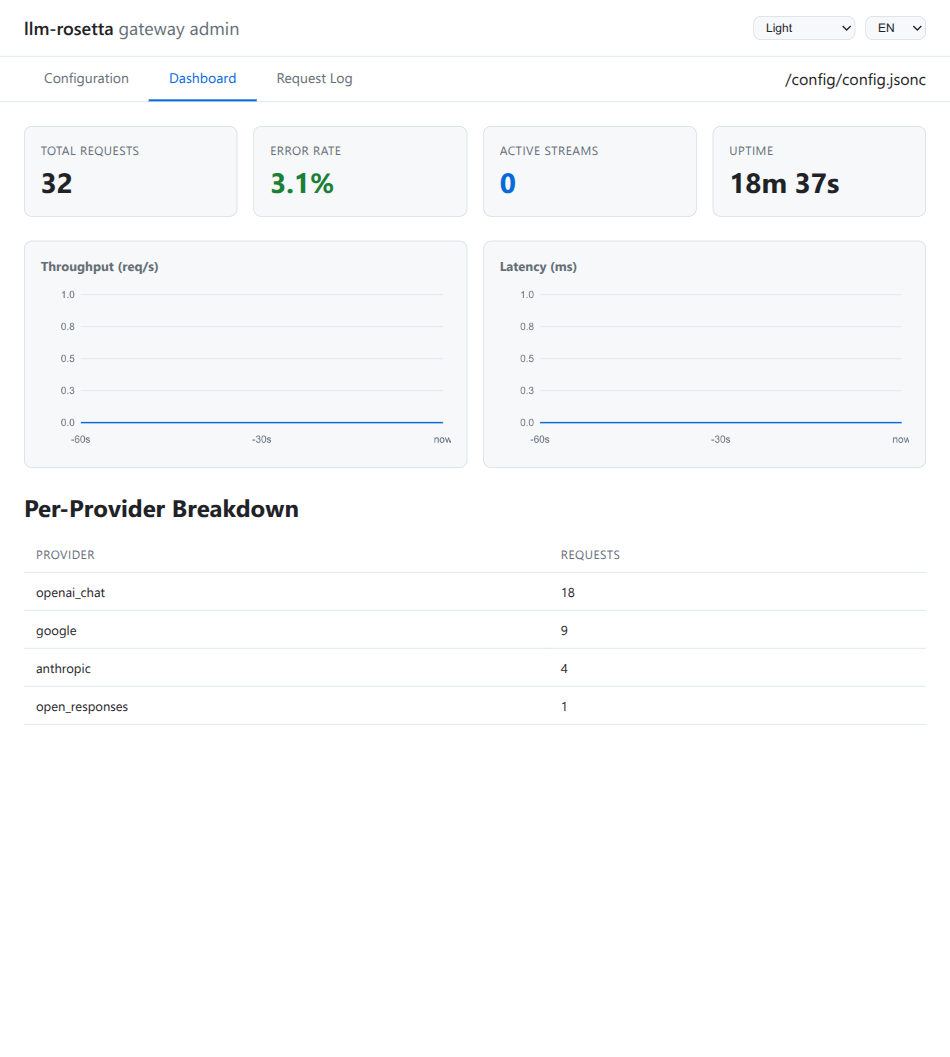
The gateway is a backend for Claude Code, Codex CLI, Aider, Antigravity CLI, OpenCode and Kilo Code, and a translating proxy in front of Ollama — see CLI Integrations.
Supported Formats
| Model type | Formats | Gateway routes |
|---|---|---|
| LLM (chat) | chat_completions, open_responses, messages, google_generate, google_interactions | /v1/chat/completions, /v1/responses, /v1/messages, /v1beta/models/…, /v1beta/interactions |
| Embeddings | openai, cohere, jina, voyage, google_generate, minimax | /v1/embeddings |
| Rerank | jina, cohere, voyage | /v1/rerank, /v2/rerank |
| Decisions | systemone, openai_decisions | /v1/decisions, /v1/systemone |
Every format converts both to and from the IR, for requests and responses; chat
formats also convert streamed chunks. open_responses is the vendor-neutral
Open Responses spec; the OpenAI profile (openai--open_responses shim) adds its
resp_ IDs, store: true and echo fields.
Provider Shims
Vendors differ from the base format in field names, defaults, auth and URL paths. A shim declares those differences, so converters stay generic. 39 shims ship with the package across 19 vendor prefixes, including Anthropic, Cohere, DeepSeek, Google, Jina, MiniMax, Moonshot, OpenAI, OpenRouter, Qwen, Volcengine, Voyage, xAI and Zhipu.
Most shim names are <vendor>--<format> — openrouter--open_responses,
deepseek--chat_completions, anthropic--messages. A few single-lane shims keep
the bare vendor name — moonshot, qwen, xai and zhipu — while their
embedding and rerank siblings carry the suffix. A provider with a bare format type
(for example type: open_responses) is vendor-neutral and must set base_url; a
vendor shim supplies the default URL and credential environment variable. A shim
can also carry a credential exchange (auth.py) and a quota probe (quota.py). See
Provider Shims.
Compatible Servers
A server that conforms to one of these formats can be configured as an upstream. Ollama (v0.14.0+) exposes three of them, so the gateway can sit in front of it in any of those dialects:
| Ollama endpoint | Format | Since |
|---|---|---|
/v1/chat/completions | chat_completions | early versions |
/v1/responses | open_responses | v0.13.3 |
/v1/messages | messages | v0.14.0 |
Other compatible servers — including vLLM, Hugging Face TGI and LM Studio — can work through the formats they expose.
Features
- Bidirectional conversion — requests, responses and streamed chunks, with stateful stream contexts and typed stream events.
- Rich content — the IR can represent text, images, tool calls and results, reasoning/thinking, citations and token usage.
- Auto-detection — identify the source format from the body, or convert in
one step with
convert(). - IR as the application payload — keep history and orchestration state in a provider-neutral form; render it to a dialect only when calling.
- Provider shims — per-vendor field transforms, URL defaults, credential exchanges and quota probes, without per-vendor conversion code.
- Gateway — weighted round-robin and affinity routing, key rotation, failover, rate limits, request log, metrics, error dumps and a usage report.
- Admin console — manage providers, models, keys, logs and settings without hand-editing config.
- No third-party dependencies on Python ≥ 3.11 — Python 3.10 adds only
typing_extensions, a backport of the standard library'stypingmodule; the gateway vendors its HTTP stack.
Installation
Library
pip install llm-rosetta
Requires Python ≥ 3.10.
Install the Gateway
pip install llm-rosetta-gateway
# Transitional alias (kept for one release) that installs both distributions:
pip install "llm-rosetta[gateway]"
Docker (Alpine, ~21 MB):
docker run -p 8765:8765 -v /path/to/config:/config oaklight/llm-rosetta-gateway
Compliance Testing
llm-comply is a companion tool that validates LLM API endpoints against official specs. Use it to verify that a gateway or proxy correctly implements the OpenAI Chat, Open Responses, Anthropic Messages and Google GenAI formats.
pip install llm-comply

# Test your gateway endpoint
llm-comply -u https://your-gateway/v1 -k $API_KEY -m your-model --format openai-chat
A hosted version is available at llm-comply.service.oaklight.top. The repository also ships an on-demand Compliance workflow.
Documentation
- English: https://llm-rosetta.readthedocs.io/en/latest/
- 中文: https://llm-rosetta.readthedocs.io/zh-cn/latest/
Citation
If you use LLM-Rosetta in your research, please cite our paper:
@article{ding2026llm,
  title={LLM-Rosetta: A Hub-and-Spoke Intermediate Representation for Cross-Provider LLM API Translation},
  author={Ding, Peng},
  journal={arXiv preprint arXiv:2604.09360},
  year={2026}
}
Contributing
Contributions are welcome! Read CONTRIBUTING.md and the contributing guide before opening a pull request.
Community
Feel free to discuss the project via GitHub Issues or the LINUX DO community.
License
This project is licensed under the MIT License — see the LICENSE file for details. The name and the logo marks are brand assets and are covered separately by TRADEMARKS.md.
Tag summary
Content type
Image
Digest
sha256:9bac0cc47…
Size
21.1 MB
Last updated
2 days ago
docker pull oaklight/llm-rosetta-gateway:dev